A.I. & Software

Run a 27B AI model on a roughly $400 AMD mini PC, give an old Quadro K6000 a 156K-token context, or run a local model entirely on your CPU. Kindi 0.3 expands affordable local AI beyond NVIDIA—with AMD support, faster prompt caching, new models and a preview of Kindi Bridge.
Download Kindi, check your card and read the updated manual:
https://amirhusain.com/software/kindi/
Watch Kindi 0.2.0 — four NVIDIA GPU families, two-card inference and 27B models:
https://www.youtube.com/watch?v=z9btEzjmz60
Watch the original Kindi video — where this started on a $15 GPU:
https://www.youtube.com/watch?v=ddAnghj8HpE
WHAT'S NEW
• AMD Radeon 780M / RDNA3 support through ROCm. Custom RDNA3 WMMA int8 and FP16 kernels bring Kindi beyond NVIDIA. A roughly $400 mini PC with 64 GB of unified RAM runs the full 27B model; prompt reading is 1.7× faster than llama.cpp in our tests. That is prompt processing, not a claim of faster output on every AMD workload.
• NVIDIA Nemotron 3.5 Bolt E4B and Gemma 4 support. Ground-up custom CUDA work, including gemma4.cu, token-for-token BPE tokenization, OpenAI-compatible tool calls and thinking mode with streaming reasoning_content.
• Quadro K6000: 27B on a 12 GB Kepler card, with a maximum context of 156,672 tokens!!! This roughly $70 used workstation GPU writes 9.9× faster than llama.cpp on the same card in our benchmark. The listing shown in the video is about $80 including shipping.
• Multi-branch prompt caching: up to 25× faster in the tested cached workload, taking queries on 9K-token documents from 10.7 seconds to 0.42 seconds. Branch Parking (KINDI_PARK_BRANCH=1) lets multiple agent conversations branch from a common prompt without duplicating the shared prompt's memory.
• Multi-GPU, multi-server installer: install.sh scans the machine and provisions independent servers per card or tensor-parallel pairs, plus a CPU companion, in one run. Includes recommended configurations and a dry-run option.
• CPU acceleration with AVX-512 / AVX2 ternary execution. On an AMD Ryzen 9 7940HS, the 2B model writes at 64.8 tok/s versus llama.cpp's 23.6 tok/s—about 2.7× faster. The video also covers the older Core i7-8700.
• Kindi Bridge preview: a curses/tmux terminal workbench pairing the pi coding agent with live Hardware Vitals, streaming token throughput and GPU cycling with Alt-G. Watch the live GTX 1080 / 27B code-review demo. Bridge is described in this recording as arriving separately in the following days.
• In-place conversation unparking: .set() copies replace temporary device-allocation bursts, eliminating that source of out-of-memory crashes when VRAM is packed at 64K+ context.
• RTX 30-series GPU-Unlock detection: the installer detects supported consumer Ampere cards, including RTX 3060 and 3080, with half-rate FP16 driver restrictions, and offers unlocking for full double-rate FP16 Tensor Core performance. This is an optional installer step.
• Interactive model catalog: kindi models and kindi use let you inspect, SHA-256 verify, download, quantize and switch among supported 2B, 4B, 9B, 27B and Nemotron models without editing configuration files.
Also in this update: the searchable “Will Kindi work on my card?” database, measured and community-reported compatibility, and an expanded field manual.
CHAPTERS
00:00 Kindi 0.3: local AI beyond NVIDIA
00:53 Check your card: the compatibility database
02:13 The updated field manual
03:00 New models: Nemotron support
03:52 Quadro K6000: 27B on a budget
05:37 Multi-branch prompt caching
07:20 Installer changes and dry run
07:59 GPU-Unlock for supported cards
09:15 Automatic hardware and model setup
09:55 CPU inference on affordable hardware
11:49 AMD mini PCs: GPU and CPU together
13:01 Kindi Bridge preview
14:02 Live demo: reviewing C code with pi
16:42 VRAM stability and the model catalog
17:57 Share your hardware results
Benchmarks are from our test systems and the release figures accompanying this update; speeds depend on model, context, hardware and settings. Maximum context and peak output speed are separate measurements. Used hardware prices vary.
What hardware are you running? Share your GPU or CPU, model, context length, read/write tok/s and Kindi version in the comments.
#Kindi #LocalAI #LocalLLM
GitHub: https://github.com/ahtx/kindi

Join The Family:💻👩🏻💻https://cyberflow-academy.framer.website/
Check Out The Courses We Offer: https://cyberflow-academy.framer.website/courses
Educational Purposes Only.
On October 29, 2026, approximately $6.3 BILLION in cryptocurrency was drained from Binance wallets across 10 blockchains, with most of the funds moving in roughly 20 minutes. Blockchain intelligence firm TRM Labs attributed the attack to North Korea's TraderTraitor hacking group, the same group linked to the $1.5 billion Bybit hack.
But here's what makes this attack particularly interesting: Binance says there is no evidence that any wallet private keys were leaked.
So how did the attackers bypass the security protecting billions of dollars?
In this video, we break down the Binance hack from a cybersecurity perspective, following the suspected attack chain from a compromised DevOps engineer's laptop to internal service containers, unauthorized withdrawal requests, and compromised wallet signing infrastructure.
We also investigate the Ethereum side of the attack and explain how EIP-7702, Type 4 transactions, smart contract delegation, and 50 pre-signed authorizations allowed attackers to take control of a Binance hot wallet.
#hacking #ethicalhacking #bugbounty #cybersecurity #hacker #pentesting #infosec #cyberattack #hackingtools #sqlinjection #metasploit #cyberflowsacademy
→ Email: cyberflow10@gmail.com
🔗 RESOURCES & TECHNICAL REFERENCES
Official incident updates:
Binance Security Incident Update:
https://www.binance.com/en/sup....port/announcement/de
Binance Security Incident Update #2:
https://www.binance.com/en/sup....port/announcement/de
Attack analysis & threat intelligence:
TRM Labs - Binance $6.36 Billion Hack Investigation:
https://www.trmlabs.com/resour....ces/blog/north-korea
Blockaid - Technical Analysis of the Binance Hack:
https://blockaid.io/blog/binan....ce-55b-hack-using-ad
Bitquery - Binance Hack On-Chain Investigation:
https://bitquery.io/investigations/binance-hack
Ethereum & blockchain security:
EIP-7702 - Set Code for Externally Owned Accounts:
https://eips.ethereum.org/EIPS/eip-7702
Ethereum Pectra Upgrade - EIP-7702 Explained:
https://ethereum.org/roadmap/pectra/7702
Cybersecurity & threat research:
MITRE ATT&CK Framework:
https://attack.mitre.org/
CISA - Secure Cloud Business Applications:
https://www.cisa.gov/
0:00 The $6.3 Billion Binance Hack
0:38 How the Attack Started
0:54 How Signing Oracles Work
1:23 Compromising a DevOps Laptop
2:34 The EIP-7702 Exploit
3:06 The 50-Nonce Trick
4:12 How Ten Blockchains Were Affected
4:31 How to Prevent These Attacks
6:29 Binance's Response
I believe in you. You can do it. 🖤
======================
.▀█▀.█▄█.█▀█.█▄.█.█▄▀ █▄█.█▀█.█─█
─.█.─█▀█.█▀█.█.▀█.█▀▄ ─█.─█▄█.█▄█

The Biggest Hack Ever (They Stole $6.5B)
My Content is now on Spotify - https://open.spotify.com/show/....033L67tzAdThMOWGnWjr
Sources:
https://x.com/tayvano_/status/2116105558910734613
https://x.com/binance/status/2116089661408108712
https://arkm.com/explorer/entity/binance
https://crystalintelligence.co....m/investigations/bin
https://www.bbc.co.uk/news/articles/cwe8lp7zy07zo
https://www.trmlabs.com/resour....ces/blog/north-korea
Official Discord Server - https://discord.gg/cqqWYDdcBn
Follow me on X - https://www.x.com/ericparker | atericparker.bsky.social
Spotify Podcast - https://open.spotify.com/show/....033L67tzAdThMOWGnWjr
Disclaimer: The content in this video is for education and entertainment purposes to showcase the dangers of malware & malicious software. I do not encourage any form of illegal hacking or piracy.
(C) Eric Parker LLC 2026

merch! https://coffeezilla.store
sale ends november 6th.
today we're discussing the binance hack, which was the largest hack ever at ~$6.3 billion dollars.
disclaimer (updated May 2025): voidzilla is an opinion‑driven channel that comments on the news of the day under the satirical and rhetorically hyperbolic banner “CRIME IS LEGAL.” the phrase critiques what we see as a lax or uneven regulatory enforcement environment for fraud. unlike our affiliated channel Coffeezilla, which conducts detailed investigations and source‑document deep dives, and draws opinions from that, voidzilla offers rapid‑fire commentary and criticism on information already in the public domain. statements here reflect the host’s views at the moment of recording and may become outdated as facts evolve. references to “crime,” “fraud,” “scam,” or similar terms appear in a rhetorical hyperbolic context similar to “CRIME IS LEGAL.” unless we expressly state that a court has entered a final judgment, no segment should be read as a definitive finding of legal liability. viewers are urged to consult primary sources and form independent conclusions. production of this program is public‑interest commentary protected by the First Amendment and the Texas Citizens Participation Act (TCPA).
anyone featured in this program who believes a material error has occured may contact our business email with supporting documentation under the SUBJECT: "CORRECTION REQUEST". we will promptly review substantiated notices and, where appropriate, issue corrections or updates.

We almost made it through Black October. Then $6.36 billion was stolen from Binance, with most of the theft unfolding in about 20 minutes. From this wave of cyberattacks to AI swarms, secret communication channels, and “cloaked daemons,” we explore a disturbing question: what happens when protecting the internet requires AI systems we can’t afford to turn off?
______________________________________________
My Links 🔗
➡️ Twitter: https://x.com/WesRothMoney
➡️ AI Newsletter: https://natural20.beehiiv.com/subscribe
Want to work with me?
Brand, sponsorship & business inquiries: wesroth@smoothmedia.co
______________________________________________
SOURCES
Binance theft: TRM Labs investigation
https://www.trmlabs.com/resour....ces/blog/north-korea
Binance's official incident update
https://www.binance.com/en/sup....port/announcement/de
Military refrigeration failures and suspected cyberattack
https://www.militarytimes.com/....pentagon/2026/10/29/
GMO's customer security update
https://internet.gmo/en/news/article/263/
Polymarket theft: technical investigation
https://report-uri.ghost.io/po....lymarkets-csp-allowe
Oracle Health breach disclosures
https://www.beckershospitalrev....iew.com/healthcare-i
DHS employee data leak
https://www.techradar.com/pro/....security/major-us-ho
CHAPTERS
00:00 Black October
02:50 Agent Swarms
05:35 Hidden Communication
10:00 Binance Hack
16:00 Agent Conflicts
20:00 AI Defenses
24:45 Shutdown Problem
27:05 What Comes Next
#ai #cybersecurity #artificialintelligence
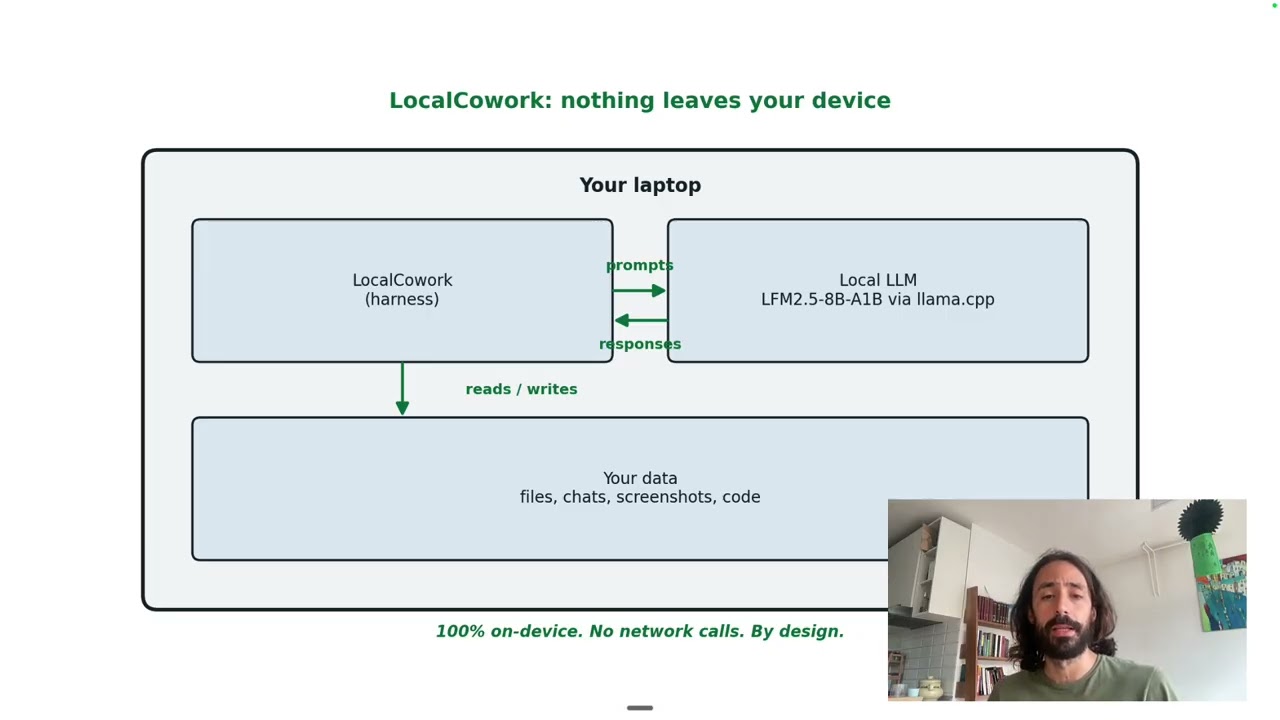
Most AI agent frameworks ship your files, screenshots, and prompts to a third-party cloud. For anything involving contracts or client data, that's not ideal.
In this demo, Pau Labarta Bajo walks through LFM2.5-8B-A1B, a mixture-of-experts model that can run entirely on a MacBook Pro with 16GB of RAM, paired with LocalCowork, an open-source agent harness from the Liquid AI cookbook. Everything stays on-device: Model, harness, data. He demos two examples including querying system info and scanning a directory for leaked secrets. If you're building for environments where data can't leave the device, this is a concrete look at what's possible on consumer hardware.
LocalCowork harness (Liquid AI cookbook repository): https://github.com/Liquid4All/cookbook
Subscribe for more from Liquid AI: https://www.youtube.com/@liquid-ai-inc
Follow @AI.Indeed to stay up to date with AI Trends, prospective of influential persons and learn something New Every time!🚀
Why Liquid AI: The Future of Private AI! How Liquid AI Unlocks Gen AI Instantly! 💧🤖! - Ramin Hasani, Co-Founder & CEO, Liquid AI
Liquid AI is a New Type of AI in the Industry which does not use #transformer architecture, uses very minimal compute and can enable enterprises to use #GenAI within no time. This helps you when you don't have access to cloud infrastructure and also where your data is sensitive and want to use private AI. It also Smarter, Faster, and More Secure! 🔒
Do you guys agree ?
Credits: @peterdiamandis (YT)
#techeducation #artificialintelligence #security #privacy #private #infrastructure #privacymatters #shortsviral #shortsvideo
Disclaimer: All rights and credits reserved to the respective owner. DM for credits or removal requests (no copyright intended).

Timestamps:
00:00 - Intro
01:10 - Model Overview
02:25 - Audio Model Overview
02:50 - Prof. Bijan on Speech Models
03:51 - Voice Chat Model Testing
07:14 - Vision Model Testing
08:01 - VLM Circuit Diagram Test
08:44 - VLM YouTube Scathing Critique Test
10:32 - VLM OCR Test
10:56 - VLM Car Identification Test
11:37 - VLM Detailed Analysis Test
12:23 - Instruct Model Testing
12:37 - Instruct Model Tool Calling
13:25 - Instruct Model Chat Testing
14:11 - Instruct Model Movie Riddle
14:59 - Instruct Model Random Chatting
15:28 - Instruct Model Browser OS Test
16:01 - Instruct Model Roleplay Test
16:21 - Voice Chat Model Conversation Testing
19:25 - Voice Model VRAM Mention
20:50 - Closing Thoughts
AI Integration & Consulting https://bijanbowen.com
Join The Discord: https://discord.gg/hfaR2exy7S
In this video, we take a hands-on look at the Liquid AI LFM2.5 model lineup, including their micro-vision, instruction, and speech-to-speech models. This release focuses on efficient multimodal capability, combining vision understanding, native audio interaction, and tool-calling within compact model architectures.
We begin with an overview of the models, then move into real-world testing across voice conversations, vision-language tasks, OCR, diagram analysis, object identification, and detailed visual reasoning. We also explore the instruction model’s tool-calling behavior, browser-based OS interactions, roleplay, and general chat performance.
HF Link: https://huggingface.co/LiquidAI
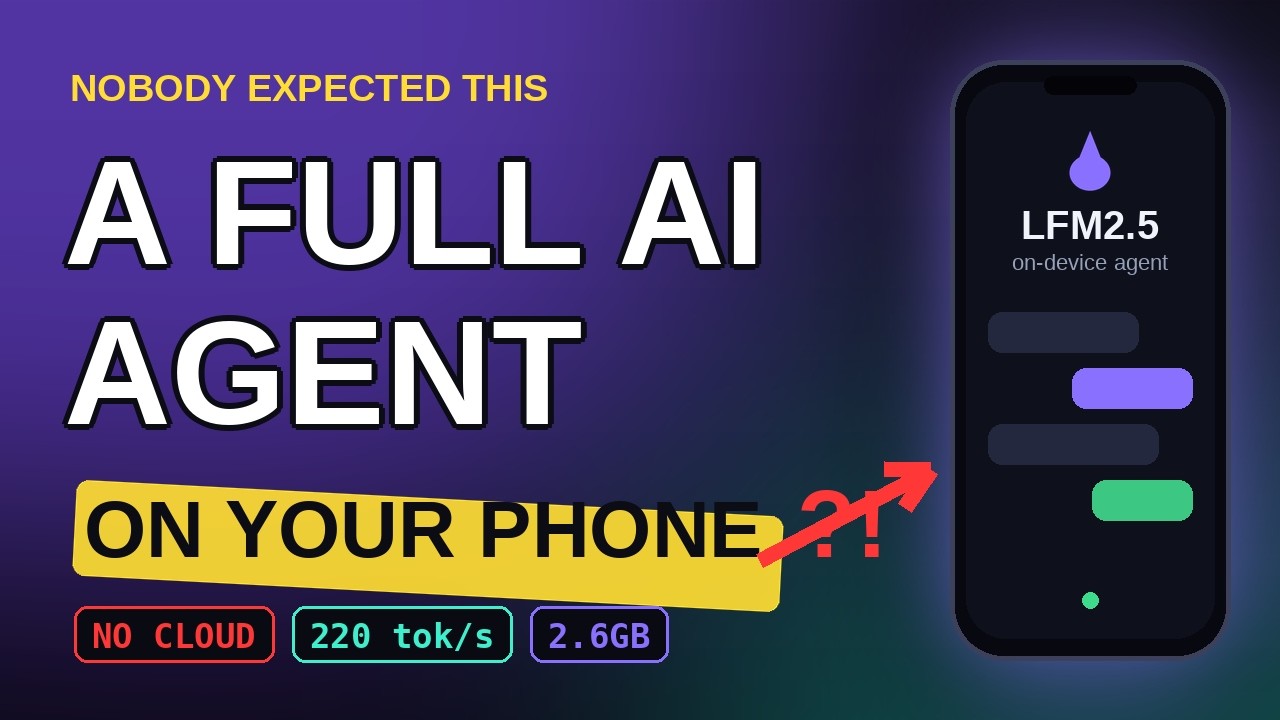
Liquid AI just released LFM2.5-2.6B — an open-weight agentic model small enough to run on a phone, fast enough to stay responsive on a plain CPU, and capable enough to plan, call tools, and work through real multi-step tasks. No cloud, no per-token bill, and your data never leaves the device.
In this video: what makes it special, the specs, on-device speed (220 tok/s on an M5 Max, ~30 tok/s on a phone), how it beats models nearly 4x its size on instruction-following and tool use, the four-stage training recipe that gets it there, the reaction on X, and how to run your own local agent in two steps.
Model & docs:
• Blog: https://www.liquid.ai/blog/lfm2-5-2-6b
• Weights: https://huggingface.co/LiquidAI/LFM2.5-2.6B
• Docs: https://docs.liquid.ai/lfm/models/lfm25-2.6b

🔹 Liquid AI has released LFM2.5-2.6B, a compact model designed to run capable AI agents directly on laptops and mobile devices.
🔹 The model was pretrained on roughly 34 trillion tokens, extended to a 128K context window, and post-trained using SFT, specialist teachers, multi-domain on-policy distillation, and Agentic RL.
🔹 It focuses on tool calling, instruction following, and multi-step agent workflows while competing with significantly larger models.
🔹 Liquid AI reports decode speeds of up to 220 tokens/s on an Apple M5 Max and 113 tokens/s on an AMD Ryzen AI Max+ 395.
🔹 We examine why efficient local models could make private, low-cost, always-available AI agents practical on everyday devices.
#LiquidAI #LFM25 #OnDeviceAI #AIAgent #AgenticAI #AgenticRL #LocalLLM
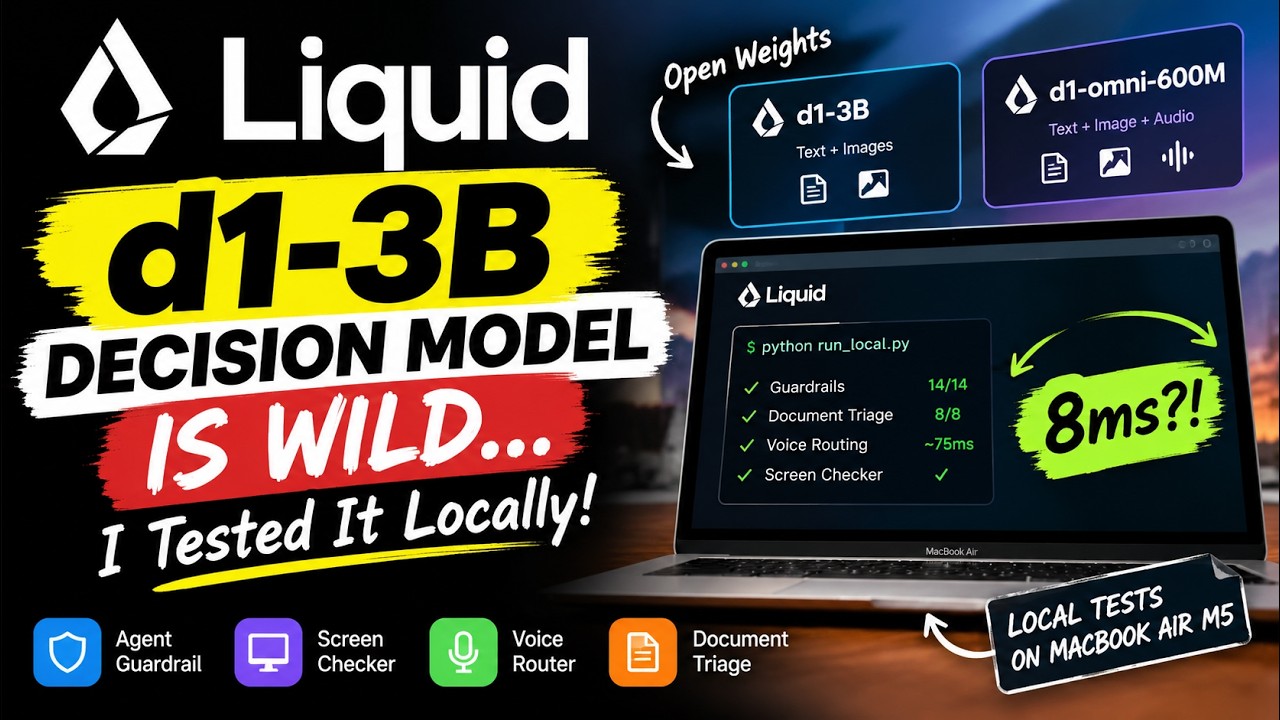
Liquid AI just released Open d1, two open-weight decision models that answer questions in one forward pass without writing a single token.
d1-3B handles text and images, and the tiny d1-omni-600M takes text plus an image or audio, with a walkthrough of both architecture diagrams.
I ran both locally on my MacBook Air M5 with an agent guardrail, a screen checker, a voice command router and a document triage test.
d1-3B scored 14/14 on guardrails and 8/8 on documents, while omni routed voice commands in about 75 ms but managed only 2/8 on documents.
Benchmarks, edge latency, real limits, and whether you should swap your label-only LLM calls for d1.
Sources:
Liquid AI blog: https://www.liquid.ai/blog/d1-open
Liquid AI launch thread on X: https://x.com/liquidai/status/2107878924831379676
d1-3B on Hugging Face: https://huggingface.co/LiquidAI/d1-3B
d1-omni-600M on Hugging Face: https://huggingface.co/LiquidAI/d1-omni-600M
Liquid docs, decision models: https://docs.liquid.ai/lfm/models/decision-models
Live camera demos (HF Space): https://huggingface.co/spaces/....LiquidAI/system-one-
Ramin Hasani spent a decade studying a 2-millimeter worm. He ended up building one of the most contrarian AI companies on the planet.
302 neurons. No brain. Yet the worm controlled 95 muscles better than any robot ever built. Ramin modeled it, solved a differential equation unsolved for over 100 years, and published it in Nature Machine Intelligence. He woke up to an inbox full of term sheets he never asked for.
That paper became Liquid AI.
In this ICONS episode, Ramin walks through the full story: from academia to MIT, the discovery of liquid neural networks, why he built on the exact opposite thesis to every other foundation model company, what two years at Vanguard taught him about trillion-dollar businesses, and what he believes the world looks like in 25 years when humans stop talking entirely.
Chapters:
00:00 Teaser
01:07 Introduction — Who is Ramin Hasani?
03:36 Life as an AI CEO: 18-hour days across Tokyo, Middle East, San Francisco
07:05 From Iran to Italy to Vienna — how he ended up in academia
11:59 C. Elegans: the worm with 302 neurons that controls 95 muscles
16:16 The discovery of liquid neural networks
18:57 Parking a car with 12 neurons
21:56 The unsolved equation: 100 years of neuroscience cracked
25:23 Nature Machine Intelligence, Hacker News, and the inbox that changed his life
27:02 Transformer architecture — and why it hits an energy wall
28:46 Liquid foundation models: exponential energy cut to linear
30:32 The jump from academia to company
40:09 Why Liquid AI raised $270M while others raised $20B
41:44 1.4 million downloads per week vs. Nvidia
52:28 Mercedes-Benz: closed in four months
53:42 Shopify: foundation models powering product search
59:44 The talent war: winning 3 out of 10 against Anthropic, xAI, Meta
01:04:26 The taste test: machine learning is an art
01:13:21 The goal: 50% of all devices by 2029
01:16:49 25 years from now: humans will stop talking
01:24:23 Rapid fire
About Ramin Hasani:
Persian-Austrian AI scientist and CEO of Liquid AI. Discovered liquid neural networks during his PhD at TU Vienna and MIT. Raised $270M at a $2.2B valuation. Partners include Mercedes-Benz, Shopify, Samsung, and AMD.
#RaminHasani #LiquidAI #FoundationModels #AIArchitecture #MachineLearning #DeepTech #EnterpriseAI #FounderStory #ICONS #ArtificialIntelligence
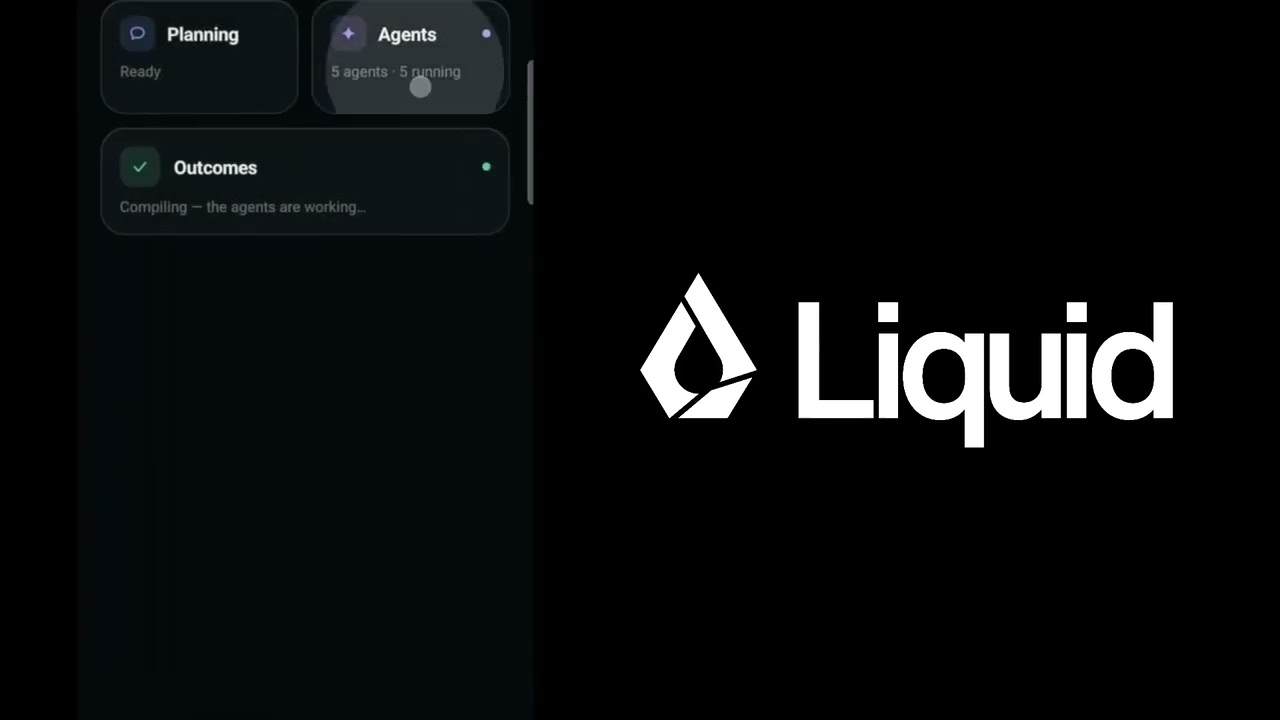
LFM2.5-2.6B is a 2.6B parameter agentic model small enough to run on a phone, fast enough to stay responsive on a CPU, and capable enough to power agentic workflows: planning, calling tools, and tackling multi-step tasks.
In this demo, a wedding invite lands at 3:45 AM and a swarm of local agents springs into action: reading the email, checking the calendar, researching travel logistics, building an outfit mood board, and spinning up dedicated agents for flights, hotel, rental car, and wardrobe, each running on its own schedule, in the background, and entirely on-device.
Because local inference is free, agents like this can run in parallel around the clock, at no marginal cost per token.
Get the models: https://huggingface.co/LiquidAI/LFM2.5-2.6B
Read the full release: https://www.liquid.ai/blog/lfm2-5-2-6b
Is training on AMD hardware actually viable in 2026? For years, the narrative has been that AMD Instinct GPUs are great for inference but a nightmare for training due to software fragmentation. This is not true anymore.
In this video, I fine-tune our Liquid AI's LFM2.5-1.2B-Instruct using the AMD Instinct MI325X GPUs.
💡 The Hardware Context:
For those unfamiliar, the AMD MI325X is the direct competitor and equivalent to the NVIDIA H200. It is the current heavy-duty workhorse for AI, boasting over 256GB of HBM (memory). While it isn't the absolute newest silicon on the market, it represents the tier of hardware that most serious labs are deploying right now.
🛠️ The Stack:
The most impressive part of this demo isn't the speed, it's the simplicity.
OS: Linux (Ubuntu)
Driver: ROCm 7.1
Libraries: Standard PyTorch + Hugging Face Transformers
Provider: Tensorwave
There are no custom Docker containers, no obscure forks, and no complex kernel hacks. If you know how to fine-tune on Nvidia, you now know how to fine-tune on AMD.
At MACHINA 2026, Ramin Hasani, CEO & Co-Founder of Liquid AI, delivered a keynote, "Intelligence for All." A conversation on making powerful AI accessible and usable for everyone, not just large-scale players.
👍 Enjoyed this session? Like, share your thoughts in the comments, and subscribe for more conversations like this.
🔗 Stay connected with MACHINA:
Website: http://machinasummit.com/
X (Twitter): https://x.com/machinasummit
LinkedIn: https://www.linkedin.com/company/machinasummit
Instagram: https://www.instagram.com/machinasummit/

Meet LFM3 by Liquid AI! Discover this new AI model, its features, capabilities, and potential for local AI applications. Watch till the end to learn what makes LFM3 worth exploring!
================================
Subscribe 2nd channel here: https://www.youtube.com/@AIPhyOx
================================
=============================================
Follow on twitter : https://x.com/Codedigipt
Follow Codedigipt channel on WhatsApp: https://whatsapp.com/channel/0....029Vb8SzEP89inlpgnxK
========= Resources =========================
https://www.liquid.ai/blog/lfm3
=============================================
#OpenSourceAI #aicoding #aiagents #artificialintelligence #chatgpt #claudecode #automation #aitools #productivity #technews #ai2026
Disclaimer:
The content in this video is for informational and educational purposes only. All opinions expressed are my own. I am not a licensed professional, and this video should not be considered professional advice. Performance benchmarks are based on specific tests and may not reflect all use cases. Always do your own research and consult with a qualified expert where necessary.
Use the information provided at your own risk.
Some links or products mentioned may be affiliate links, which means I may earn a small commission at no extra cost to you. Thank you for your support!
How do you know whether an AI model is actually reasoning over biological data, or just producing fluent answers? LongevityBench, our new benchmark published in Cell with Insilico Medicine, tests models across 17 tasks spanning clinical records, DNA methylation, transcriptomics, proteomics, and genetics. Our compact LFMs outperformed every frontier model we evaluated on several of them.
Katerina Nasto, Liquid AI researcher, and our CTO Mathias Lechner walk through how the benchmark was built, why leakage-proof evaluation matters, and how specialized models that run locally on sensitive patient data could help researchers move from prediction toward better hypotheses and experiments.
Read more and check out the model: https://www.liquid.ai/blog/longevitybench
Full paper: https://shorturl.at/qJZLO

When a model generates a molecule, you don't find out if it worked until you've synthesized it in the wet lab. That makes the learning signal sparse and hallucinations expensive.
In this interview, CTO Mathias Lechner talks with co-founder and Chief Science Officer Alexander Amini about building Liquid Foundation Models (LFMs) for modalities beyond text: biology, audio, vision, and time series. Alexander explains why efficiency is a direct advantage in biology, where a single input, such as a human genome, can run to billions of base pairs, and points to Liquid's partnership with Insilico Medicine as an early example in drug discovery.
Subscribe to follow every interview: https://www.youtube.com/@liquid-ai-inc
Careers at Liquid AI: https://www.liquid.ai/careers
Timestamps:
00:00 - Intro
00:49 - First Look
02:03 - Technical Look
03:11 - Browser OS Test
04:53 - PC Repair Website Test
05:57 - Roleplay Test
08:43 - Biography Website Test
09:23 - Simple Tool Calling Test
10:02 - Difficult Tool Calling Test
13:46 - Tool Calling Test Results
14:44 - General Knowledge Test
15:59 - Simple Python Test
17:34 - Good Looking Website Test
19:09 - Closing Thoughts
AI Integration & Consulting: https://bijanbowen.com/
Join the Discord: https://discord.gg/hfaR2exy7S
In this video, we take a hands-on look at Liquid LFM2.5-8B-A1B, a small on-device MoE model from Liquid AI designed for local AI workflows.
We test the model across a range of practical tasks including browser-based workflows, website generation, roleplay, general knowledge, Python coding, and tool calling. The goal is to see how useful a small active-parameter MoE model can be when used in real-world scenarios rather than just benchmarks.
In this interview from theCUBE + NYSE Wired: Robotics & AI Infra Leaders 2026, Ramin Hasani, co-founder and chief executive officer of Liquid AI, joins theCUBE's John Furrier and Howie Xu to discuss how specialized, efficient AI models are powering intelligence at the edge. Hasani explains how Liquid Foundation Models bring specialized intelligence outside the data center, running on devices as small as a Raspberry Pi. He details a new production deal with Mercedes-Benz, where a 600-megabyte multimodal model powers in-car voice intelligence on low-cost automotive processors. Hasani argues that intelligent routing across cloud, sovereign and device-based models is key to cutting inference costs, while small models thrive on fine-tuned specialization rather than general-purpose reasoning.
The conversation explores why Liquid AI moved beyond the transformer architecture, addressing the exponential compute and memory costs created by growing context windows and KV cache demands. Hasani notes that frontier labs, including Moonshot's Kimi models, are now adopting similar efficiency-first design principles. He and Xu debate the networking challenges of distributed, on-device intelligence, and outline emerging opportunities in AI for science, materials discovery and robotics. The discussion also touches on the risks of AI-generated content saturation and the industry's shift toward continual learning as models move from static systems to adaptive ones. Hasani closes by pointing to cybersecurity and edge privacy as fertile ground for the next wave of AI entrepreneurship, offering a grounded view of where efficient, specialized intelligence is headed next.
Find more SiliconANGLE news and analysis https://siliconangle.com/
Follow theCUBE's wall-to-wall event coverage https://siliconangle.com/events/
Learn about the latest theCUBE events https://www.thecube.net/
00:00 - Foundations and Frontiers of AI: Innovations, Efficiency, and Ethics
04:08 - AI Innovation Amid Economic and Automotive Dynamics
06:42 - Optimizing and Specializing Small AI Models: Challenges and Solutions
08:59 - Reimagining AI: Alternatives and Edge Considerations
12:56 - Balancing AI: Exploring Opportunities and Addressing Content Saturation Concerns
18:42 - Advancing AI: Continuous Learning and Future Trajectories
#theCUBE #RoboticsAIInfraLeaders #theCUBEresearch #NYSEWired #LiquidAI #EdgeAI

Liquid AI just dropped LFM2-VL, and it feels like a turning point. These are the world’s fastest, best-performing open-source small foundation models, built to run directly on phones, laptops, and even wearables. With up to 2× faster inference than rivals, device-aware efficiency, and benchmarks rivaling much larger systems, Liquid AI is showing that multimodal AI doesn’t need the cloud anymore. From smart cameras to offline assistants, this release proves advanced vision-language AI can finally live on everyday devices.
📩 Brand Deals & Partnerships: me@faiz.mov
✉ General Inquiries: airevolutionofficial@gmail.com
🦾 What You’ll See:
• Why LFM2-VL is the fastest open-source small foundation model
• How 2× faster inference changes real-world AI applications
• The clever architecture — from pixel unshuffle to native resolution patches
• Benchmarks that rival larger closed models while running locally
• Why Liquid AI’s open release could shift the AI industry off the cloud
🚨 Why It Matters:
LFM2-VL isn’t just another model — it’s proof that advanced multimodal AI can now run offline, privately, and efficiently on devices people already own. This could mark the beginning of AI moving away from giant servers and into our pockets.
#ai #ainews #aitools

Meet LFM3-1.7B from Liquid AI: a groundbreaking 1.73B parameter edge agent LLM powered by a novel tri-hybrid architecture running at 256K context in just 1 GB of VRAM. Liquid LFM3 achieves unprecedented prefill acceleration and outscores much larger models on browser automation and function calling benchmarks like WebArena and BFCL V4.
In this deep-dive walkthrough, we benchmark LFM3 across local hardware, evaluate its multi-turn tool harnesses, and run three fully offline production workflows: an autonomous WebArena-style browser action sequencer, a 256K long-document legal compliance auditor, and a structured edge API micro-gateway.
🚀 Full Local Setup Guide: https://github.com/47thtechcor....ner/RayCodes_LFM3-1.
🔥 To support the channel: https://ko-fi.com/prayasjain
🗃️ Official Tool Repo: https://huggingface.co/LiquidAI/LFM3-1.7B
#LiquidAI #LFM3 #EdgeAI

Descubre cómo aprovechar el potencial de los modelos pequeños de IA con el nuevo LFM 2.5 de Liquid AI. En este video analizamos cómo un modelo de apenas 0.23B de parámetros puede ser extremadamente eficiente para ejecutar tareas específicas sin necesidad de la potencia de un modelo gigante.
Aprenderás a configurar y ejecutar modelos ultra ligeros utilizando llama.cpp y formatos GGUF para optimizar tus recursos de hardware. Veremos casos de uso reales donde la velocidad y el bajo consumo de VRAM superan con creces a modelos más grandes, permitiendo una automatización mucho más ágil.
Exploramos la implementación técnica mediante archivos .bat, la configuración de parámetros de muestreo y pruebas de rendimiento en GPU. Analizamos aplicaciones prácticas como el filtrado masivo de palabras clave mediante Python y la capacidad de estos modelos para la selección de herramientas (tool use) en entornos de programación.
📝 Índice:
00:00:00 Introducción a los modelos LFM 2.5 de Liquid AI
00:01:20 Configuración y descarga en llama.cpp
00:03:03 Pruebas de velocidad y respuestas en español
00:05:24 Limitaciones y razonamiento del modelo
00:06:14 Caso práctico: Filtrado de palabras clave con Python
00:09:28 Prueba de uso de herramientas (Tool Use)
00:11:45 Conclusión: Cuándo usar modelos pequeños
Si este video te ayuda, suscríbete para ver más tutoriales sobre inteligencia artificial, automatización y creación de contenido.
#InteligenciaArtificial #LiquidAI #LlamaCPP #ModelosDeLenguaje #AutomatizaciónIA
✅ Canal WhatsApp: https://www.whatsapp.com/chann....el/0029VbCR3SKId7nGT
Contacto: nichonauta@gmail.com
Sitio web: nichonauta.com
At Snapdragon Summit 2026, Cristiano Amon, CEO of Qualcomm, sits down with Ramin Hasani, CEO and Co-founder of Liquid AI, to discuss the future of local AI and agentic systems.
The conversation covers Liquid Context on Snapdragon, Liquid’s smart memory layer for AI systems running close to the user. Ramin explains how shared context across devices can enable more proactive agents across phones, cars, PCs, wearables, and other devices.
Read the full release: https://www.liquid.ai/blog/liquid-context-qualcomm

Join My Newsletter for Regular AI Updates 👇🏼
https://forwardfuture.ai
My Links 🔗
👉🏻 Subscribe: https://www.youtube.com/@matthew_berman
👉🏻 Twitter: https://twitter.com/matthewberman
👉🏻 Discord: https://discord.gg/xxysSXBxFW
👉🏻 Patreon: https://patreon.com/MatthewBerman
👉🏻 Instagram: https://www.instagram.com/matthewberman_ai
👉🏻 Threads: https://www.threads.net/@matthewberman_ai
👉🏻 LinkedIn: https://www.linkedin.com/company/forward-future-ai
Media/Sponsorship Inquiries ✅
https://bit.ly/44TC45V

Spun out of MIT CSAIL, four founders - Ramin Hasani, Mathias Lechner, Alexander Amini, and Daniela Rus, started Liquid AI with the mission of building state-of-the-art, general-purpose AI systems that are capable, efficient, highly aligned, and trustworthy.
On this panel at Imagination In Action’s ‘Forging the Future of Business with AI’ Summit, Hasani and Amina discuss how the company thinks about AI and how they plan to make it more efficient.
Subscribe to FORBES: https://www.youtube.com/user/F....orbes?sub_confirmati
Fuel your success with Forbes. Gain unlimited access to premium journalism, including breaking news, groundbreaking in-depth reported stories, daily digests and more. Plus, members get a front-row seat at members-only events with leading thinkers and doers, access to premium video that can help you get ahead, an ad-light experience, early access to select products including NFT drops and more:
https://account.forbes.com/membership/?utm_source=youtube&utm_medium=display&utm_campaign=growth_non-sub_paid_subscribe_ytdescript
Stay Connected
Forbes newsletters: https://newsletters.editorial.forbes.com
Forbes on Facebook: http://fb.com/forbes
Forbes Video on Twitter: http://www.twitter.com/forbes
Forbes Video on Instagram: http://instagram.com/forbes
More From Forbes: http://forbes.com
Forbes covers the intersection of entrepreneurship, wealth, technology, business and lifestyle with a focus on people and success.

Want to make money and save time with AI? Get AI Coaching, Support & Courses 👉 https://www.skool.com/ai-profit-lab-7462/about
Get the video notes + links to the tools → https://www.skool.com/ai-profit-lab-7462/about
Get a FREE AI Course + 1000 NEW AI Agents 👉 https://www.skool.com/ai-seo-w....ith-julian-goldie-15
Want to know how I make videos like these? Join the AI Profit Boardroom → https://www.skool.com/ai-profit-lab-7462/about
Get a FREE AI SEO Strategy Session: https://go.juliangoldie.com/st....rategy-session?utm=j
Local Vision AI is Here! Liquid AI’s LFM2VL is Insanely Fast
Discover how Liquid AI’s new LFM2VL vision language model runs directly in your browser without servers or API costs. This breakthrough enables ultra-fast, private image analysis using your own GPU, changing the economics of AI development forever.
00:00 - Intro: AI Inside Your Browser
01:12 - What is Liquid AI LFM2VL?
01:38 - Model Sizes and Parameters
02:46 - The Tech: Why it is So Fast
04:37 - WebGPU and Local Inference
05:31 - Real-time Video Captioning Demo
05:52 - Real-world Business Use Cases
07:38 - AI Success Lab and Resources

Want to make money and save time with AI? Get AI Coaching, Support & Courses 👉 https://www.skool.com/ai-profit-lab-7462/about
Get the video notes + links to the tools → https://www.skool.com/ai-profit-lab-7462/about
Get a FREE AI Course + 1000 NEW AI Agents 👉 https://www.skool.com/ai-seo-w....ith-julian-goldie-15
Want to know how I make videos like these? Join the AI Profit Boardroom → https://www.skool.com/ai-profit-lab-7462/about
Get a FREE AI SEO Strategy Session: https://go.juliangoldie.com/st....rategy-session?utm=j
This Tiny 350M AI Model Is Insane: Liquid AI LFM-2.5 Explained
Liquid AI just released LFM-2.5 350M, a tiny model that runs locally on your phone or browser with incredible speed. Discover how this intelligence density powerhouse is shifting the future of AI from massive cloud models to efficient, specialized local agents for business automation.
00:00 - Intro: The Liquid AI Revolution
01:09 - The Problem with Big AI Models
01:45 - LFM-2.5: High Intelligence Density
02:31 - Defining Agentic Workflows
03:44 - Running AI in Your Web Browser
04:53 - Real-World Business Automation
05:43 - LFM-2.5 vs GPT-4 Comparison
06:27 - The Future of Local AI Agents

In this conversation with QuantumBlack, AI by McKinsey, Ramin Hasani explains why liquid foundation models are a game-changer for enterprise AI. Learn how these models deliver efficiency, reliability, and control, powering high-quality generative AI across devices, at the edge, and in low-latency settings, all while cutting costs and energy use.
Read the full interview here: https://www.mckinsey.com/capab....ilities/quantumblack
Subscribe to our channel: http://mck.co/YouTube
Subscribe to our newsletters: http://mck.co/Subscribe
***Find us on***
Facebook: http://mck.co/Facebook
Twitter: http://mck.co/Twitter
LinkedIn: http://mck.co/LinkedIn
Instagram: http://mck.co/Instagram

Post-training has become a major part of building useful AI systems.
In this interview, Liquid’s post-training team, including Maxime Labonne, Edoardo Mosca, and Jiahui Wang, discuss how post-training turns base models into models with specific capabilities: Following instructions, using tools, handling long-context environments, and carrying out multi-step tasks.
They also discuss Antidoom, Liquid’s work on reducing “doom loops” in small models and why post-training is especially important for building reliable on-device agentic models.
Read our release on reducing doom loops: https://www.liquid.ai/blog/antidoom
Careers at Liquid AI: https://www.liquid.ai/careers

In this interview from Fully Connected 2026, Jeffrey Li, chief operating officer of Liquid AI Inc, joins theCUBE's John Furrier and Dave Vellante to discuss how Liquid AI is redesigning foundation models from the ground up to bring production-quality intelligence to edge devices. Li explains why traditional transformer architectures, with their exploding KV caches, cannot fit within the fixed compute of phones, cars and wearables, prompting Liquid to build non-transformer models suited to constrained environments. He details Liquid Context, a new layer developed with Qualcomm that captures personal, physical-world signals only a device can see and feeds them to agents so they can act more proactively on a user's behalf.
The conversation also explores how Liquid AI partners with CoreWeave to train its specialized, alternative-architecture models, even though the resulting systems run far outside the data center. Li discusses the company's portfolio approach, spanning nearly a 1,000x range in model sizes to match everything from phones to beefier edge infrastructure such as telecom central offices. He breaks down how edge deployment simplifies data governance by keeping information on-device, and how Liquid balances latency, cost and privacy to decide what runs locally versus in the cloud. Li also points to Liquid's production deployment with Mercedes-Benz and a newly released vision model as proof points of its edge-first strategy. From quality gaps to integration hurdles, he outlines what's still holding industries like telecom back from full-scale edge AI adoption, and how Liquid is working to close that gap.
Find more SiliconANGLE news and analysis https://siliconangle.com/
Follow theCUBE's wall-to-wall event coverage https://siliconangle.com/events/
Learn about the latest theCUBE events https://www.thecube.net/
00:00 - Unveiling Liquid AI: Infrastructure, Vision, and Edge Innovations
02:09 - Challenges of Harnessing AI on Devices
04:50 - Optimizing and Evaluating Non-Transformer Models
06:56 - Navigating Edge and Cloud: Integration and Decision-Making
08:59 - Navigating CoreWeave: Innovations, Future Directions, and Edge Deployment
12:39 - Advancing Through Collaboration and Integration
#theCUBE #FullyConnected #theCUBEresearch #LiquidAI #CoreWeave #EdgeAI #Qualcomm

Liquid AI released LFM2.5-24B-A2B on Oct 13, 2026. It’s a 24B-parameter mixture-of-experts model with 2.45B active, 131K context, built for agents.
Liquid AI’s benchmarks show it leading or matching Qwen3.6-35B-A3B on 5 of 8 agentic tests (LiveClaw 48.09 vs 38.19, AutomationBench 27.69 vs 8.72). The bigger model still wins on GPQA and SWE-bench Verified.
Liquid AI reports 184 tok/s on an M5 Max, and API pricing of $0.10 per 1M input tokens and $1.00 per 1M output tokens.
I ran it locally on a 24 GB MacBook Air M5 (Q4_K_M via llama.cpp). It passed text, long-context (23K tokens) and 5 tool-calling agent tests. Vision ran through the LFM2.5-VL-3B sibling model, because the 24B model is text-only.
Sources: Liquid AI blog https://www.liquid.ai/blog/lfm2-5-24b-a2b | Launch post https://x.com/liquidai/status/2110055807194931348
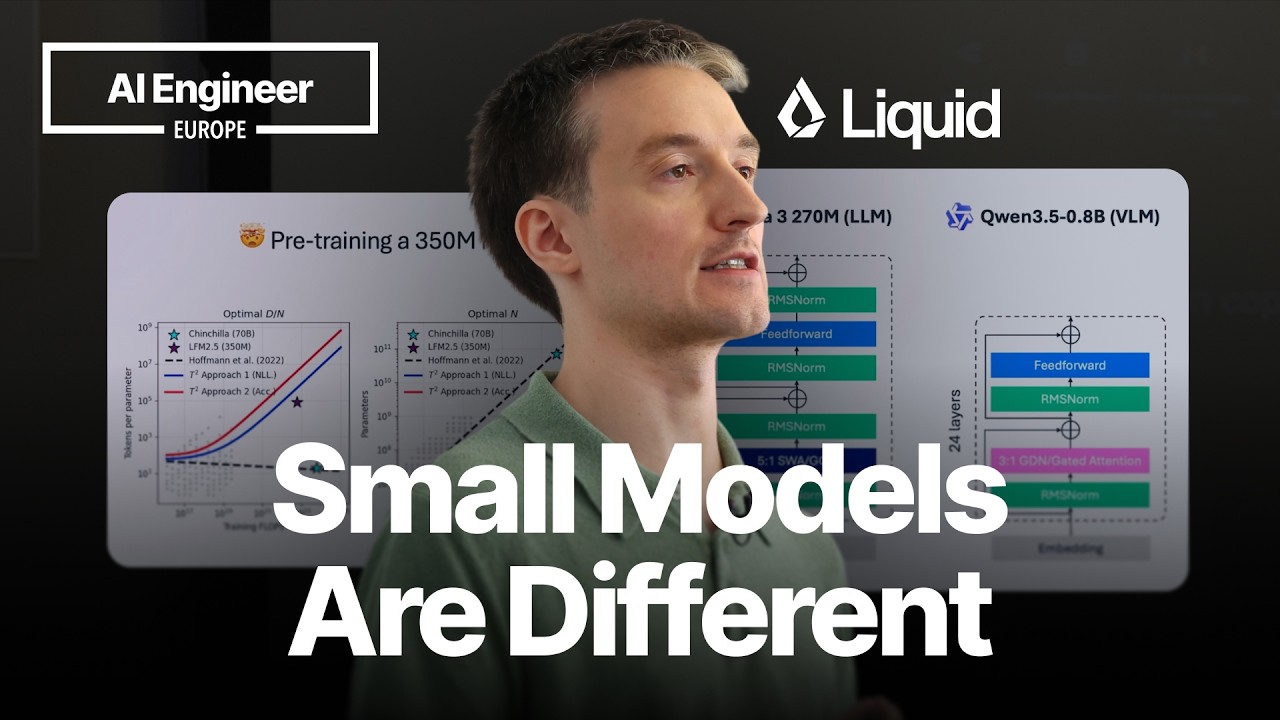
A new class of small models is emerging with the ability to reliably follow instructions and call tools while running on-device under 1 GB of memory. In this talk, we'll break down how to post-train frontier small models using the LFM2.5 recipe: on-policy preference alignment, agentic reinforcement learning, and curriculum training with iterative model merging. We'll cover training challenges unique to the 1B scale, like doom loops, capability interference, and how to fix them. The goal is to give you a concrete playbook to fine-tune and deploy small models for your own use cases, from structured data extraction to multi-turn tool use.
Speaker info:
- https://x.com/maximelabonne
- https://www.linkedin.com/in/maxime-labonne/
- https://github.com/mlabonne
Timestamps:
0:00:00 - Start
0:00:14 - Introduction to frontier small models at Liquid AI
0:01:02 - Characteristics: memory-bound, task-specific, latency-sensitive
0:02:20 - Architecture: why large embedding layers are inefficient
0:04:01 - LFM2 architecture: using gated short convolutions for speed
0:06:09 - LFM 2.5 recipe: 28T tokens and post-training stages
0:08:34 - Post-training: SFT, preference alignment, and RL best practices
0:10:43 - Identifying "doom loops" in reasoning models
0:11:34 - Solutions: mitigating loops via preference alignment and RL
0:15:29 - Future focus: using agentic tools to overcome memory limits
0:17:58 - Q&A: real-world applications for small vs. large models
---
Watch along with the corrected transcript, summary, timestamps and resources on this talk's official AIE page:
https://ai.engineer/talks/fLUt....UkqYHnQ-everything-i
Join our upcoming AI Engineer conferences (see https://ai.engineer landing page):
- AIEi Shanghai, November 5–6 — the first for meeting top Chinese labs and engineers
- AIE CODE in SF, November 10–12 — the top AI Coding conference returns
- AIEi Sydney, December 7–8 — the first AIEi run alongside NeurIPS 2026 in Sydney
---
LFM 2.5 is officially out, letting us run LFM2.5 24B locally without cloud costs. In this guide, we walk through the complete Liquid AI LFM2.5 local setup to test the new LFM2.5-24B-A2B hybrid architecture. This Liquid AI model uses an active 2B parameter footprint to deliver ultra-fast local reasoning, outperforming larger alternatives in automated agent benchmarks.
We test LFM2.5 GGUF quantizations in Ollama to find the best balance for consumer hardware. Learn how to install LFM2.5 offline, configure the low-temperature inference flags, and run autonomous agentic coding tools directly on mid-tier GPUs and budget laptops with zero API limits.
🚀 Full Local Setup Guide: https://github.com/47thtechcor....ner/RayCodes_LFM-2.5
🔥 To support the channel: https://ko-fi.com/prayasjain
🖥️ Official Model Repo: https://huggingface.co/LiquidA....I/LFM2.5-24B-A2B-GGU
#LFM25 #LiquidAI #OpenSourceAI
How can countries build sovereign AI while reducing the cost of advanced computing?
Ramin Hasani, Co-Founder & CEO of Liquid AI, joins Manus Cranny at the FII TV Studio during FII PRIORITY Europe 2026 in Rome to discuss the capital costs of sovereign AI, the evolution of semiconductor technology, and how more efficient chips are reshaping the future of AI infrastructure.
Watch the full interview for insights on sovereign AI, semiconductors, innovation, and the future of computing.
#FIIPRIORITY #EuropeReimagined
This video locally installs and tests LFM2.5-24B-A2B; built for fast, private agents on-device.
📬Weekly AI Newsletter: https://fahdmirza.substack.com/
🔥 Get 50% Discount on any A6000 or A5000 GPU rental, use following link and coupon:
https://bit.ly/fahd-mirza
Coupon code: FahdMirza
🔥 Buy Me a Coffee to support the channel: https://ko-fi.com/fahdmirza
#lfm25 #lfm24b
PLEASE FOLLOW ME:
▶ LinkedIn: / fahdmirza
▶ YouTube: / @fahdmirza
▶ Blog: https://www.fahdmirza.com
00:00 Intro: DairyFlow app and the hidden bug
00:50 Meet LFM2.5-24B-A2B
01:15 Giving the goal to Hermes Agent
02:28 Post-training recipe
02:28 Bug fix result and live proof
04:39 Tattoo simulation test
05:27 Liquid's benchmark chart vs Qwen
07:30 81-language test
09:20 Deep sea submarine physics test
10:39 Secret Wedding Test
11:10 Final verdict
RESOURCES:
▶ https://huggingface.co/LiquidA....I/LFM2.5-24B-A2B-GGU
All rights reserved © Fahd Mirza

Get the Agent OS & Liquid AI Masterclass 👉 https://www.skool.com/ai-profit-lab-7462/about
Want to make money and save time with AI? Join here: https://www.skool.com/ai-profit-lab-7462/about
Liquid AI's DSpark: 3.18x Faster Local AI is Here!
Discover how Liquid AI's new DSpark draft model is revolutionizing local AI performance by making LFM 2.5 models up to 3.18x faster. We break down the technology behind speculative decoding and show you how to build high-speed AI agents for your business today.
00:00 - Intro
00:22 - What is DSpark?
00:54 - How it Works
01:23 - Speed Benchmarks
02:04 - LFM 2.5 Models Explained
04:49 - AI Agent Workflows
07:49 - Free AI Resources
Want to make money and save time with AI? Join here: https://www.skool.com/ai-profit-lab-7462/about
Video notes + links to the tools 👉 https://www.skool.com/ai-profit-lab-7462/about
Get a FREE AI Course + Community + 1,000 AI Agents 👉https://www.skool.com/ai-seo-w....ith-julian-goldie-15
Free GEO & AI SEO Checklist! https://orders.goldie.agency/signup
Get a FREE GEO + AEO Strategy Session → https://go.juliangoldie.com/st....rategy-session?utm=j
Get 200+ Free AI SEO Prompts → https://go.juliangoldie.com/ch....at-gpt-prompts?utm=j
Get our free SEO Link Building Book here: https://go.juliangoldie.com/opt-in?utm=julian
Liquid AI’s D1 Ultra is a new AI model that never writes a word, yet it claims the top spot on the Artificial Analysis Decision Index. Learn what a “decision model” is, how it gives fast yes/no answers, labels, and scores with honest confidence, and the one thing to check before trusting any leaderboard.
00:00 Intro – The AI That Never Writes
00:40 What Is D1 Ultra? – Decision Model Explained
01:19 3 Question Types – Yes/No, Choice, Score
01:56 Why It Stands Out – Calibration
03:02 Not a Chatbot – Use It as a Specialist
03:30 D1 Model Lineup – Ultra, D1, 3B, Omni
03:54 Image Input – Text and Photos
04:26 Live Demos – Defects and Wordle
04:52 Benchmarks – Artificial Analysis Index
06:00 How to Try It – API and OpenRouter
06:30 Speed and Cost – Tokens and Latency
06:46 Limits – What It Can’t Do
07:14 Verdict – Test It on Your Data
AI systems are getting more powerful, but the infrastructure needed to support them is under increasing pressure. In this episode of a new series featuring Liquid experts, our CTO Mathias Lechner speaks with CEO Ramin Hasani about the growing gap between AI demand and the energy required to power it.
🚀 Liquid AI LFM3 is HERE! Can a tiny 1.7B parameter model outperform models nearly 5× its size?
In this video, I’m exploring Liquid AI’s brand-new LFM3 family, featuring six specialized AI models designed for text generation, vision, audio, multimodal intelligence, and agentic workflows.
But here’s the exciting part! I’m running LFM3-1.7B completely locally on my Apple Mac mini M6 with 32GB unified memory, achieving approximately 70 tokens per second (TPS) while using it with OpenClaw!
Even more surprisingly, I’m observing around 70 TPS when my OpenClaw conversation context reaches nearly 80% utilization!
Chapters:
00:00 - Introduction
05:06 - LFM3 with LM Studio
06:04 - OpenClaw with LFM3
09:48 - LFM3 with Pi Coding Agent
Get 85% discount of my course from the discount Coupon code https://www.udemy.com/course/a....i-red-teaming-prompt
My OtherAI related Courses for you to empower today:
Learn my latest course launched this week on ZERO Code AI Tests: Automate Software Tests in Plain English: https://www.udemy.com/course/z....ero-code-ai-testing/
Use code: LEARN_OCT_26 for 85% OFF (limited time)
My Other AI related Courses for you to empower today:
To Learn more about building your own AI Agents and Testing AI Agents, follow the courses below available in Udemy with Discount coupon codes.
Use coupon code : LEARN_OCT_26
🤖 AI-Driven Test Automation: Playwright, Selenium, LLMs & More
https://www.udemy.com/course/a....i-test-automation-se
🤖 https://www.udemy.com/course/g....enai-multi-agent-sof
🤖Test AI & LLM App with DeepEval, RAGAs & more using Ollama
https://www.udemy.com/course/a....i-testing-deepeval-r
🤖Build & Test AI Agents, ChatBot, RAG with Ollama & Local LLM
https://www.udemy.com/course/b....uild-ai-agent-chatbo
🤖2025 - Understand ,Test ,Fine-tune AI Model with HuggingFace
https://www.udemy.com/course/a....i-with-huggingface/?
🤖2025 - Using Generative AI in Software Automation Testing
https://www.udemy.com/course/g....enerative-ai-in-soft
➜ Discount coupon codes for all the courses: LEARN_OCT_26
► [Advanced Framework development Course in Selenium C#] https://www.udemy.com/course/f....ramework-development
► [Advanced Framework development Course in Playwright C#]
https://www.udemy.com/course/f....ramework-development
#LiquidAI #LFM3 #OpenClaw #MacMiniM6 #LocalLLM #AppleSilicon #AgenticAI #Qwen #LocalAI #AIModels #ExecuteAutomation
► [Udemy] https://www.udemy.com/user/karthik-kk/
► [XUnit with Selenium] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Git Basics] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [SpringBoot for Testing] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
Selenium and C#
► [C# for automation testing] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium with C#] https://www.youtube.com/watch?v=mluLgBywW0Y&list=PL6tu16kXT9PqKSouJUV6sRVgmcKs-VCqo
► [BDD with Specflow] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [BDD with Selenium] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium .NET Core] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
Selenium &Java
► [Cucumber with Selenium] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Cucumber with Selenium] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Cucumber 4 Upgrade] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium Grid] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium framework development] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium 4] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium Grid with Docker] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
In this video, I test Liquid AI's latest 24B Mixture-of-Experts (MoE) model on my Mac mini M6, exploring its real-world performance, inference speed, and integration with OpenClaw using a 128K context window.
What makes LFM2.5-24B-A2B interesting is its efficient architecture. Although the model has 24 billion parameters, it activates only around 2.45 billion parameters per token, making it an interesting option for running powerful AI agents locally.
LFM2.5 24B A2B - https://huggingface.co/LiquidAI/LFM2.5-24B-A2B
Chapters:
00:00 - Introduction
02:46 - Running LFM2.5 24B A2B in LM Studio
04:23 - Running LFM2.5 24B A2B with OpenClaw
06:46 - Using Apple Shortcuts for Powerful Operation
12:19 - Using LFM2.5 2.6B with Mirai Uzu
Get 85% discount of my course from the discount Coupon code https://www.udemy.com/course/a....i-red-teaming-prompt
My OtherAI related Courses for you to empower today:
Learn my latest course launched this week on ZERO Code AI Tests: Automate Software Tests in Plain English: https://www.udemy.com/course/z....ero-code-ai-testing/
Use code: LEARN_SEP_26 for 85% OFF (limited time)
My Other AI related Courses for you to empower today:
To Learn more about building your own AI Agents and Testing AI Agents, follow the courses below available in Udemy with Discount coupon codes.
Use coupon code : LEARN_OCT_26
🤖 AI-Driven Test Automation: Playwright, Selenium, LLMs & More
https://www.udemy.com/course/a....i-test-automation-se
🤖 https://www.udemy.com/course/g....enai-multi-agent-sof
🤖Test AI & LLM App with DeepEval, RAGAs & more using Ollama
https://www.udemy.com/course/a....i-testing-deepeval-r
🤖Build & Test AI Agents, ChatBot, RAG with Ollama & Local LLM
https://www.udemy.com/course/b....uild-ai-agent-chatbo
🤖2025 - Understand ,Test ,Fine-tune AI Model with HuggingFace
https://www.udemy.com/course/a....i-with-huggingface/?
🤖2025 - Using Generative AI in Software Automation Testing
https://www.udemy.com/course/g....enerative-ai-in-soft
➜ Discount coupon codes for all the courses: LEARN_OCT_26
► [Advanced Framework development Course in Selenium C#] https://www.udemy.com/course/f....ramework-development
► [Advanced Framework development Course in Playwright C#]
https://www.udemy.com/course/f....ramework-development
#LiquidAI #LFM25 #OpenClaw #MacMiniM6 #LocalLLM #AppleSilicon #AIModels #AgenticAI #LocalAI #LLMBenchmark #ExecuteAutomation
► [Udemy] https://www.udemy.com/user/karthik-kk/
► [XUnit with Selenium] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Git Basics] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [SpringBoot for Testing] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
Selenium and C#
► [C# for automation testing] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium with C#] https://www.youtube.com/watch?v=mluLgBywW0Y&list=PL6tu16kXT9PqKSouJUV6sRVgmcKs-VCqo
► [BDD with Specflow] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [BDD with Selenium] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium .NET Core] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
Selenium &Java
► [Cucumber with Selenium] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Cucumber with Selenium] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Cucumber 4 Upgrade] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium Grid] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium framework development] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium 4] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
► [Selenium Grid with Docker] https://www.youtube.com/playli....st?list=PL6tu16kXT9P
This video explores how Liquid AI’s LFM2.5-VL-1.6B model achieves high-performance vision and language tasks directly within a web browser using WebGPU. We break down the "Efficiency by Design" philosophy and the hybrid architecture that allows this 28-trillion token model to run locally in under 1GB of RAM. Stick around for a live demo of real-time webcam captioning to see how this private, offline-capable AI performs on standard consumer hardware.
🔗 Relevant Links
LFM2.5-VL-1.6B https://www.liquid.ai/blog/int....roducing-lfm2-5-the-
Hugging Face WebGPU Demo: https://huggingface.co/spaces/....LiquidAI/LFM2.5-VL-1
❤️ More about us
Radically better observability stack: https://betterstack.com/
Written tutorials: https://betterstack.com/community/
Example projects: https://github.com/BetterStackHQ
📱 Socials
Twitter: https://twitter.com/betterstackhq
Instagram: https://www.instagram.com/betterstackhq/
TikTok: https://www.tiktok.com/@betterstack
LinkedIn: https://www.linkedin.com/company/betterstack
📌 Chapters:
00:00 Intro
00:16 Local Processing with WebGPU and ONNX Runtime
00:48 Understanding the Liquid Foundation Model (LFM)
01:25 Efficiency by Design: How it Fits Under 1GB of RAM
02:22 Native Resolution and Tiling Strategy
03:05 Live Demo: Real-time Webcam Captioning
04:51 Final Thoughts And Takeaways

At Snapdragon Summit 2026, Jeffrey Li, COO of Liquid AI, presents Liquid Context, our smart memory layer for AI systems running close to the user.
The demo shows how shared context across devices can enable more proactive agents across phones, cars, PCs, wearables, and other devices.
Read the full release: https://www.liquid.ai/blog/liquid-context-qualcomm

Want to make money and save time with AI? Join here: https://www.skool.com/ai-profit-lab-7462/about
Video notes + links to the tools 👉 https://www.skool.com/ai-profit-lab-7462/about
Get a FREE AI Course + Community + 1,000 AI Agents 👉https://www.skool.com/ai-seo-w....ith-julian-goldie-15
Order AI SEO here → https://go.juliangoldie.com/backlink-portal
Free GEO & AI SEO Checklist! https://orders.goldie.agency/signup
Get a FREE GEO + AEO Strategy Session → https://go.juliangoldie.com/st....rategy-session?utm=j
Get 200+ Free AI SEO Prompts → https://go.juliangoldie.com/ch....at-gpt-prompts?utm=j
Get our free SEO Link Building Book here: https://go.juliangoldie.com/opt-in?utm=julian
Liquid AI’s new LFM3 vision model has just 1.9B parameters, yet it matches a model over 6X its size across 62 vision tests. Learn how the tri-hybrid design works, what the six-model family can do on your own device, and the jobs the small text model is NOT built for.
00:00 Intro – Tiny AI vs. 6X bigger model
01:03 LFM3 Family – All 6 models explained
02:06 Vision Model – Beats giants on 62 tests
03:32 Vision Skills – Video, spatial, robotics
03:56 Tri-Hybrid Design – Why small works
04:52 Text Model – 1GB, runs on any phone
05:34 What NOT to Use It For – Save time
05:50 Speed Test – Phone and laptop results
06:14 Fine-Tuning – Customize on one GPU
06:40 How to Try It – Free weights and tools
07:20 Quick Start – 3 steps to test it
07:32 Final Takeaway – Small, focused models

Discover how the Liquid Engine enables custom intelligence at every scale for your applications.
Find out more: https://www.liquid.ai
Outline:
00:00 - Introduction
00:10 - Liquid Engine
00:35 - Advantages
00:50 - Use cases
Liquid AI, an MIT spin-off, is a foundation model company headquartered in Boston, Massachusetts. Our mission is to build capable and efficient general-purpose AI systems at every scale.
Liquid AI’s CSO and Co-Founder Alexander Amini joins Sophia Dew on MTS Live to discuss the LFM2 model family, the latest LFM2.5-24B-A2B release, and recent research with Insilico Medicine, published in Cell, on using foundation models to better understand aging biology.
Learn more:
LFM2.5-24B-A2B - https://www.liquid.ai/blog/lfm2-5-24b-a2b
Our longevity research - https://www.liquid.ai/blog/longevitybench
Full MTS segment: https://x.com/i/broadcasts/1DxLdZLpyYbxm
Meet LFM3, Liquid AI's new generation of Liquid Foundation Models.
Built on one shared backbone, the LFM3 family spans text, vision, audio, omni, and decision models. These compact models are designed to be specialized, fine-tuned, and deployed wherever your application runs, from edge devices to private infrastructure and the cloud.
Read more: https://www.liquid.ai/blog/lfm3
---
Connect with Liquid AI:
• Careers: https://www.liquid.ai/careers
• Hugging Face: https://huggingface.co/LiquidAI
• Discord: https://discord.com/invite/liquid-ai
• X: https://x.com/LiquidAI
• LinkedIn: https://www.linkedin.com/company/liquid-ai-inc/
• GitHub: https://github.com/Liquid4All/cookbook
• Substack: https://liquidai.substack.com/
• Luma: https://luma.com/liquid.ai
---
Musicbed SyncID: MB01JC3XBJ8GXYS

Liquid AI is a foundation model company building efficient, capable AI across every scale. Everyone on the team is an expert in their own right, coming together from industry and academia to solve massive challenges. This is a look at the people and the mission behind the models.
Explore open roles at Liquid AI: https://www.liquid.ai/careers

On January 5, 2026 at CES, our CEO Ramin Hasani announced the release of LFM2.5, our most capable family of on-device foundation models to date, to the world with Lisa Su and AMD.
LFM2.5 builds on the LFM2 architecture introduced last year, with major advances in training scale, reinforcement learning, and multimodal support, pushing what’s possible in the ~1B parameter class.
This release reflects a clear design philosophy: maximize intelligence per unit of compute so high-quality AI can run locally, in real time, across CPUs, GPUs, and NPUs—without relying on cloud inference.
In this clip, Ramin walks through why efficiency, latency, and deployability, not raw scale, will define the next phase of AI adoption.
LFM2.5 is open-weight and available now.
The future of on-device intelligence is here.
Read the full release: https://lnkd.in/e_6RmVZU
Timestamps:
00:00 - Intro
01:04 - First Look
01:59 - Technical Look
03:10 - Model Weights Overview
04:22 - LFM3 1.7B Test
05:48 - 1.7B Hermes Agent Test
11:41 - Vision Model Test
16:35 - Voice Model Test
21:23 - Omni Model Test
23:43 - Edge Device Test
25:30 - Closing Thoughts
Join the Discord: https://discord.gg/hfaR2exy7S
Peri Robot: https://github.com/OminousIndustries/peri
In this video, we take a hands-on look at Liquid AI LFM3, testing the new family of small local AI models designed for efficient on-device use.
We begin with a technical overview, then test the 1.7B model with Hermes agent workflows before exploring its vision, voice, and omni capabilities. We also look at how these models perform on edge devices, including phones.
